iceberg-migrate
Rewrite Apache Iceberg metadata paths after a data migration — without a JVM.



A pure-Python CLI that fixes stale paths in Iceberg table metadata after data has landed on AWS S3. Runs in seconds, not minutes. No Spark cluster. No JVM. Drop it into any post-sync pipeline.
The Problem
You move Iceberg table data to AWS S3 — via DataSync, rclone, aws s3 sync, or any other tool. The data files are there. But the metadata still contains the old source paths:
s3a://on-prem-minio/warehouse/db/events  ← stale
hdfs://namenode:8020/warehouse/db/events ← stale
/mnt/nas/iceberg/warehouse/db/events     ← stale
Athena, Glue, and EMR refuse to read the table. The metadata needs updating.
The Solution
iceberg-migrate migrate \
  --table-location  s3://my-bucket/warehouse/db/events \
  --source-prefix   s3a://on-prem-minio/warehouse \
  --dest-prefix     s3://my-bucket/warehouse
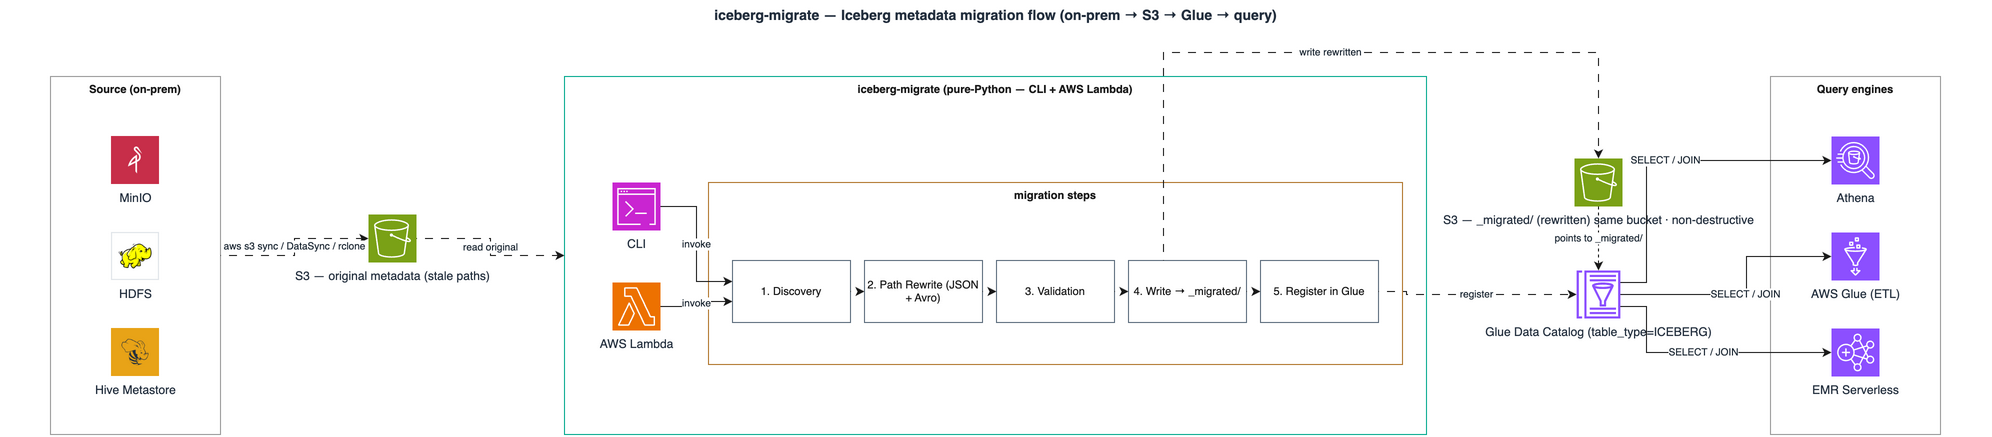
That’s it. The tool reads the Iceberg metadata tree, rewrites every path-bearing field, writes migrated copies to _migrated/, and registers the table in AWS Glue Catalog — all without touching the original files.
Two entry points share one migration core: the CLI above, and an AWS Lambda for Airflow/orchestrator integration (see docs/LAMBDA.md).
Why Not Just Use Spark?
| iceberg-migrate | Spark job | |
|---|---|---|
| Runtime | ~3 seconds | ~5 minutes (cluster warmup) |
| Dependencies | Python + boto3 | JVM, Spark, cluster or serverless |
| Infrastructure | None | EMR, Glue ETL, or local Spark |
| Runs in CI/CD | Yes | Painful |
| Source path format | Any (s3a://, hdfs://, local) |
S3 only (typically) |
The tool rewrites metadata files — JSON and Avro, typically a few kilobytes. There is no reason to spin up a cluster for this.
Verified Query Engines
Migrated tables have been end-to-end tested against three AWS query engines:
| Engine | Test type | Result |
|---|---|---|
| Amazon Athena | SQL queries via Athena API | ✅ 7 tests passing |
| AWS Glue ETL 5.1 | PySpark jobs via Glue Data Catalog | ✅ 3 tests passing |
| EMR Serverless 7.12.0 | PySpark jobs via Iceberg Glue catalog | ✅ 3 tests passing |
Every migrated table is readable for SELECT, JOIN, and cross-table joins.
Source Catalog Compatibility
The tool is source-agnostic. It handles whatever the source catalog wrote:
| Source | Metadata format | Avro codec | Status |
|---|---|---|---|
| Lakekeeper (Rust) | Gzip-compressed .gz.metadata.json |
deflate |
✅ |
| PyIceberg SQL / SQLite | Plain JSON | deflate |
✅ |
| Hive Metastore (HMS) | Plain JSON | deflate |
✅ |
| Java catalogs (Glue, Nessie, Polaris, etc.) | Plain JSON | deflate |
✅ |
| Hadoop filesystem | Plain JSON | any | ✅ |
Compression is detected from the filename extension, not file magic bytes. Avro codec is preserved exactly on round-trip — the tool never silently recompresses or decompresses Avro manifests.
Iceberg Version Support
| Format version | Supported | Notes |
|---|---|---|
| v1 | ✅ | Original format |
| v2 | ✅ | Row-level deletes (position + equality) |
| v3 | ✅ | Deletion vectors, referenced_data_file |
| v4+ | ❌ | Rejected with a clear error — prevents silent corruption |
Installation
# From source (uv)
uv sync

# Or pip
pip install .
Runtime requirements: Python ≥ 3.10, AWS credentials with S3 + Glue access.
Usage
Migrate a table
iceberg-migrate migrate \
  --table-location  s3://my-bucket/warehouse/db/events \
  --source-prefix   s3a://old-minio/warehouse \
  --dest-prefix     s3://my-bucket/warehouse
Dry run first
iceberg-migrate migrate \
  --table-location  s3://my-bucket/warehouse/db/events \
  --source-prefix   s3a://old-minio/warehouse \
  --dest-prefix     s3://my-bucket/warehouse \
  --dry-run --verbose
HDFS source
iceberg-migrate migrate \
  --table-location  s3://my-bucket/warehouse/db/events \
  --source-prefix   hdfs://namenode:8020/warehouse \
  --dest-prefix     s3://my-bucket/warehouse
JSON output for scripting
iceberg-migrate migrate ... --json 2>/dev/null | jq .statusAll options
--table-location   S3 URI of the Iceberg table root        [required]
--source-prefix    Original path prefix to replace         [required]
--dest-prefix      New S3 path prefix                      [required]
--dry-run          Show planned changes, no writes
--verbose          Print per-file substitution counts
--glue-database    Override Glue database name
--glue-table       Override Glue table name
--json             Emit JSON to stdout, summary to stderr
--aws-region       AWS region for Glue (default: env)
Lambda (Airflow / orchestrator)
Invoke synchronously with a JSON payload whose keys mirror the CLI flags in snake_case:
{
  "table_location": "s3://my-bucket/warehouse/db/events",
  "source_prefix":  "s3a://on-prem-minio/warehouse",
  "dest_prefix":    "s3://my-bucket/warehouse"
}
Returns {"status": "success", ...} on success; raises (Lambda FunctionError) on any failure so the orchestrator can retry. See docs/LAMBDA.md for the full contract, IAM requirements, and VPC/endpoint prerequisites.
What Happens Under the Hood
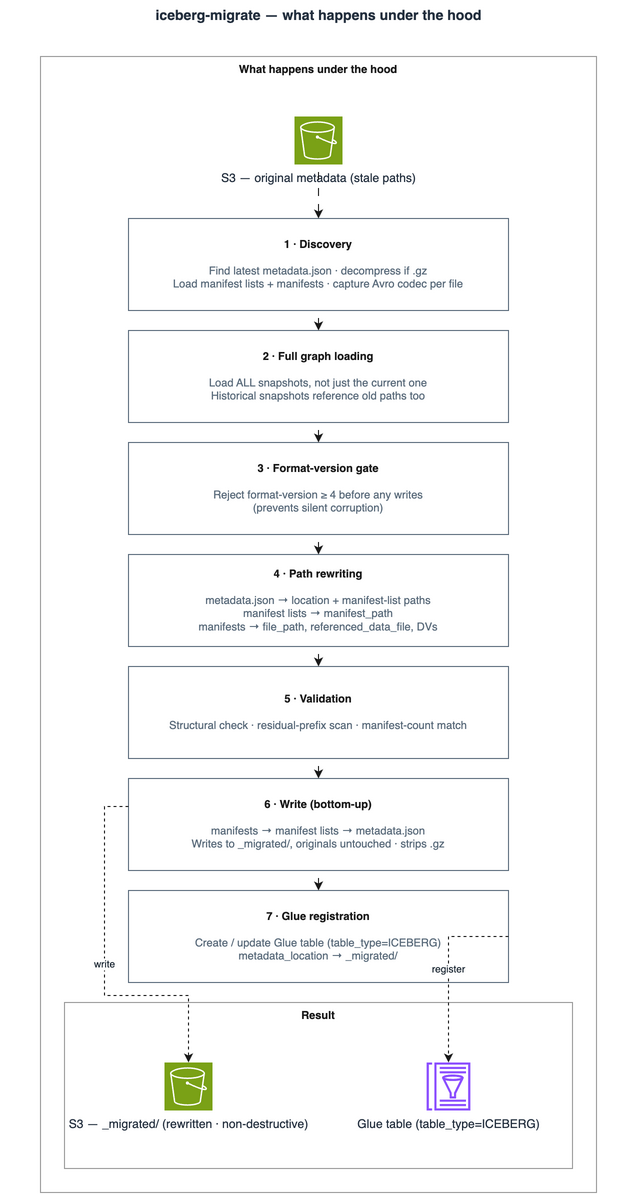
Non-destructive by design. Migrated metadata lives in _migrated/ alongside the original. Sync tools can overwrite the original metadata on the next run without affecting the migrated copy.
Project Layout
src/iceberg_migrate/
├── cli.py                   # Typer CLI entry point
├── core.py                  # Shared migration orchestration (CLI + Lambda)
├── lambda_handler.py        # Lambda entry point (thin adapter over core.py)
├── discovery/               # Locate, decompress, parse metadata from S3
├── rewrite/                 # Rewrite paths in JSON + Avro
├── validation/              # Pre-write structural + residual-prefix checks
├── writer/                  # Bottom-up S3 writer
├── catalog/                 # Pluggable catalog registration (Glue, REST)
└── output/                  # Rich human + JSON output
See docs/ARCHITECTURE.md for the module-by-module design and docs/adr/ for the decisions behind it.
Development
just test           # Unit tests (fast, no Docker)
just check          # Lint + types + unit tests
Tests use moto to mock S3 and Glue — no AWS account or cluster required.
Contributing
Contributions are welcome — issues, PRs, and discussions all help. Please run just check before opening a PR. For anything non-trivial, open an issue first so we can agree on the approach.
License
MIT © SparkLabX
Source: README.md on GitHub ↗